CSIM-001: One-layer no controller sanity check in csim
Experiment Trace
| Field | Value |
|---|---|
| Dataset | DS-AFFINE-LINEAR-000 |
| Model | MDL-DENSE1-LINEAR-NOBIAS-000 |
| Optimizer | SGD-style online loop |
| Controller | NONE |
| Precision mode | ap_fixed<16,8, AP_RND, AP_SAT> |
| Ablation focus | None |
| Drift | None |
| Learning rate |
Summary and background
This experiment is just a sanity check to make sure that the wiring of hls4ml-trainable and 🚂ENABOL is correct. We just want to synthesize our simple one-layer linear model with no controller and make sure that it can train in the csim environment without any issues. This is a necessary step before we can start testing the global throttle controllers in the csim environment, which will allow us to validate the results of the previous experiments in a more realistic setting and with more realistic quantization effects.
Setup and code
Here we will briefly describe the setup of the experiment, and then we will jump to the results. For more details on the code, please check the notebook where the code is fully documented and explained.
First, we define the global parameters for the simulation (sweep, thresholds, etc):
## Dataset and model config
N = 1000      # num samples
SEED = 42     # For reproducibility

## Controller config
CONTROLLER_NAME = "none"    # "none", "throttle", "kappa"
CHI = 1.0                   # Only for throttle, ignored for none
The creation of the dataset and the model is exactly as shown in EXP-000A and EXP-000B, so we skip the details here. Because this test does require a few utilities, we'll add them here explicitly.
Make precision utility
In the results shown here we do not sweep over different quantization/precisions, but doing so would be straightforward by just adding more precisions to the PRECISIONS variable and then looping over them in the main loop. For that reason, we create a utility to convert the model weights to a given precision, so that we can easily apply it in case we want to add quantization sweeps in the future.
Note that in this case we assume some relations between the precisions of different tensors (e.g., the gradient WL is 4 bits wider than the weight WL, etc). This is, by no means, the optimal way to do it, and it should be investigated further in the future to answer the question what is the optimal precision stack for any layer, given the precision of the weights?. For now, we just assume some relations that seem reasonable and that are consistent with what we have seen in previous experiments.
from enabol import dtypes, PrecisionDict

def make_precision_dict(BASE_WL, BASE_IWL, QMODE="AP_RND", OMODE="AP_SAT"):
    wide_weight = dtypes.ap_fixed(WL=BASE_WL, IWL=BASE_IWL, QMODE=QMODE, OMODE=OMODE)
    wide_activation = dtypes.ap_fixed(WL=BASE_WL, IWL=BASE_IWL+2, QMODE=QMODE, OMODE=OMODE)
    wide_gradient = dtypes.ap_fixed(WL=BASE_WL+4, IWL=BASE_IWL+2, QMODE=QMODE, OMODE=OMODE)
    wide_update = dtypes.ap_fixed(WL=BASE_WL+4, IWL=BASE_IWL, QMODE=QMODE, OMODE=OMODE)
    wide_accumulator = dtypes.ap_fixed(WL=BASE_WL+12, IWL=BASE_IWL+8, QMODE=QMODE, OMODE=OMODE)
    wide_loss = dtypes.ap_fixed(WL=2*BASE_WL, IWL=BASE_IWL+10, QMODE=QMODE, OMODE=OMODE)
    return PrecisionDict({
                "input": {"value": wide_activation},
                "dense0": {
                    "weight": wide_weight,
                    "activation": wide_activation,
                    "gradient": wide_gradient,
                    "update": wide_update,
                    "accumulator": wide_accumulator,
                },
                "loss": {"value": wide_loss},
            })
Create controller
In this experiment we are testing the case where no controller is used, which means that we just need to create a dummy controller that does not apply any control. This is straightforward using the enabol.Controller.from_str method, which allows us to create a controller from a string identifier. In this case, we just use the string "none" to create a controller that does nothing.
# We can start with None (default, no throttling or kappa)
controller = enabol.Controller.from_str(CONTROLLER_NAME, chi=CHI)
print(controller)
Compile and run in csim
Finally, we can compile the model and run it in the csim environment. The compilation is done using the enabol.compile function, which takes care of all the details of the compilation process, including the generation of the hls4ml project, the compilation of the C++ code, and the execution of the csim. In this case, we set csim=True to run the csim after compilation, and we set synth=False to avoid running synthesis, since we are only interested in testing the csim for now.
from enabol.compile import compile

hls_model, hls_config = compile(
    # Enabol params
    model=model,
    dataset=dataset,

    # Typical hls4ml params
    precision=precision_dict,
    backend="Vitis",
    toolchain="auto",          # resolves to kona-vitis-2024_1 on server
    part="xcku035-fbva676-2-e",
    io_type="io_parallel",
    strategy="Latency",
    reuse_factor=1,

    # Trainability
    trainable=True,
    optimizer="sgd",
    controller="none",

    # Training hyperparams
    learning_rate=0.01,
    batch_size=1,
    epochs=2,
    shuffle=True,
    log_every=10,

    # HLS config
    write=True,                # generate hls4ml project
    compile_cpp=False,         # local C++ shared-lib compile; no Vitis needed
    build=True,               # actual HLS build/csim/synth; Vitis needed
    csim=False,
    synth=False,

    # Output/workspace config
    output_dir = f"../../sandbox/{model.name}_hls",
    overwrite=True,

)
Now run csim independently:
hls_model.build(csim=True, synth=False)
which generates an output like:
****** vitis-run v2024.1 (64-bit)
**** SW Build 5074859 on 2024-05-20-23:21:20
**** Start of session at: Sat May 23 16:51:56 2026
  ** Copyright 1986-2022 Xilinx, Inc. All Rights Reserved.
  ** Copyright 2022-2024 Advanced Micro Devices, Inc. All Rights Reserved.
INFO: [vitis-run 82-31] Launching vitis_hls: vitis_hls -nolog -run tcl -f /home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls/build_prj.tcl -work_dir /home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls
****** Vitis HLS - High-Level Synthesis from C, C++ and OpenCL v2023.2 (64-bit)
**** SW Build 5069499 on May 21 2024
**** IP Build 4028589 on Sat Oct 14 00:45:43 MDT 2023
**** SharedData Build 4025554 on Tue Oct 10 17:18:54 MDT 2023
**** Start of session at: Sat May 23 16:51:58 2026
  ** Copyright 1986-2022 Xilinx, Inc. All Rights Reserved.
  ** Copyright 2022-2024 Advanced Micro Devices, Inc. All Rights Reserved.
source /mnt/raid5/fpga/cad/xilinx/Vitis_HLS/2024.1/scripts/vitis_hls/hls.tcl -notrace
INFO: [HLS 200-10] For user 'manuelbv' on host 'kona-ubuntu' (Linux_x86_64 version 6.8.0-110-generic) on Sat May 23 16:52:00 CDT 2026
INFO: [HLS 200-10] On os Ubuntu 24.04.4 LTS
INFO: [HLS 200-10] In directory '/home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls'
Sourcing Tcl script '/home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls/build_prj.tcl'
INFO: [HLS 200-1510] Running: open_project LinearBlockModel_prj
INFO: [HLS 200-10] Opening project '/home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls/LinearBlockModel_prj'.
INFO: [HLS 200-1510] Running: set_top LinearBlockModel
INFO: [HLS 200-1510] Running: add_files firmware/LinearBlockModel.cpp -cflags -std=c++0x
INFO: [HLS 200-10] Adding design file 'firmware/LinearBlockModel.cpp' to the project
INFO: [HLS 200-1510] Running: add_files -tb LinearBlockModel_test.cpp -cflags -std=c++0x
INFO: [HLS 200-10] Adding test bench file 'LinearBlockModel_test.cpp' to the project
INFO: [HLS 200-1510] Running: add_files -tb firmware/weights
INFO: [HLS 200-10] Adding test bench file 'firmware/weights' to the project
INFO: [HLS 200-1510] Running: add_files -tb tb_data
INFO: [HLS 200-10] Adding test bench file 'tb_data' to the project
INFO: [HLS 200-1510] Running: open_solution solution1
INFO: [HLS 200-10] Opening solution '/home/manuelbv/new_ENABOL/sandbox/LinearBlockModel_hls/LinearBlockModel_prj/solution1'.
INFO: [SYN 201-201] Setting up clock 'default' with a period of 5ns.
INFO: [SYN 201-201] Setting up clock 'default' with an uncertainty of 1.35ns.
INFO: [HLS 200-1611] Setting target device to 'xcku035-fbva676-2-e'
INFO: [HLS 200-1505] Using flow_target 'vivado'
Resolution: For help on HLS 200-1505 see docs.xilinx.com/access/sources/dita/topic?Doc_Version=2023.2%20English&url=ug1448-hls-guidance&resourceid=200-1505.html
INFO: [HLS 200-1464] Running solution command: config_compile -name_max_length=80
INFO: [XFORM 203-1161] The maximum of name length is set to 80.
INFO: [HLS 200-1464] Running solution command: config_schedule -enable_dsp_full_reg=0
INFO: [HLS 200-1510] Running: config_array_partition -maximum_size 4096
ERROR: [HLS 200-101] config_array_partition: Unknown option '-maximum_size'.
ERROR: [HLS 200-101] config_array_partition: Unknown option '4096'.
SEE ALSO
INI: syn.array_partition.complete_threshold syn.array_partition.throughput_driven
docs.xilinx.com/access/sources/dita/topic?Doc_Version=2023.2%20English&url=ug1399-vitis-hls&resourceid=vyw1583260160301.html
INFO: [HLS 200-1510] Running: config_compile -name_max_length 80
INFO: [XFORM 203-1161] The maximum of name length is set to 80.
INFO: [HLS 200-1510] Running: set_part xcku035-fbva676-2-e
INFO: [XFORM 203-1161] The maximum of name length is set to 80.
INFO: [HLS 200-1510] Running: config_schedule -enable_dsp_full_reg=false
INFO: [HLS 200-1510] Running: create_clock -period 5 -name default
INFO: [HLS 200-1510] Running: set_clock_uncertainty 27% default
***** C SIMULATION *****
INFO: [HLS 200-1510] Running: csim_design
INFO: [SIM 211-2] *************** CSIM start ***************
INFO: [SIM 211-4] CSIM will launch CLANG as the compiler.
INFO: [HLS 200-2036] Building debug C Simulation binaries
 Compiling ../../../../LinearBlockModel_test.cpp in debug mode
 Compiling ../../../../firmware/LinearBlockModel.cpp in debug mode
 Generating csim.exe
============================================================
ENABOL + hls4ml-trainable CSIM training run
Generated by enabol+hls4ml-trainable
ENABOL version: 0.1.0, hls4ml-trainable version: 0.0.0a
Project: LinearBlockModel | Backend: Vitis
Controller: CTRL-NONE | Optimizer: sgd | Loss: half_mse
Learning rate: 0.01 | Batch size: 1 | Epochs: 2
Shuffle: true | Shuffle seed: 13 | Log every: 10
User: manuelbv | Host: unknown | Date: 2026-05-23 16:52:13
============================================================
Epoch [1/2] - sample 1/1000: loss 3.57245, alpha: 1
Epoch [1/2] - sample 11/1000: loss 0.877808, alpha: 1
Epoch [1/2] - sample 21/1000: loss 0.24823, alpha: 1
Epoch [1/2] - sample 31/1000: loss 0.427734, alpha: 1
Epoch [1/2] - sample 41/1000: loss 0.298981, alpha: 1
Epoch [1/2] - sample 51/1000: loss 0.832886, alpha: 1
Epoch [1/2] - sample 61/1000: loss 0.261108, alpha: 1
Epoch [1/2] - sample 71/1000: loss 0.00634766, alpha: 1
Epoch [1/2] - sample 81/1000: loss 0.345734, alpha: 1
Epoch [1/2] - sample 91/1000: loss 0.0163574, alpha: 1
Epoch [1/2] - sample 101/1000: loss 0.428955, alpha: 1
Epoch [1/2] - sample 111/1000: loss 0.971191, alpha: 1
Epoch [1/2] - sample 121/1000: loss 0.0106812, alpha: 1
Epoch [1/2] - sample 131/1000: loss 0.224854, alpha: 1
Epoch [1/2] - sample 141/1000: loss 0.31192, alpha: 1
Epoch [1/2] - sample 151/1000: loss 0.222015, alpha: 1
Epoch [1/2] - sample 161/1000: loss 0.58255, alpha: 1
Epoch [1/2] - sample 171/1000: loss 0.605652, alpha: 1
Epoch [1/2] - sample 181/1000: loss 0.105408, alpha: 1
Epoch [1/2] - sample 191/1000: loss 0.517914, alpha: 1
Epoch [1/2] - sample 201/1000: loss 0.0293884, alpha: 1
Epoch [1/2] - sample 211/1000: loss 0.340454, alpha: 1
Epoch [1/2] - sample 221/1000: loss 0.0635681, alpha: 1
Epoch [1/2] - sample 231/1000: loss 0.345978, alpha: 1
Epoch [1/2] - sample 241/1000: loss 0.198425, alpha: 1
Epoch [1/2] - sample 251/1000: loss 0.145691, alpha: 1
Epoch [1/2] - sample 261/1000: loss 0.152435, alpha: 1
Epoch [1/2] - sample 271/1000: loss 0.112793, alpha: 1
Epoch [1/2] - sample 281/1000: loss 0.182434, alpha: 1
Epoch [1/2] - sample 291/1000: loss 0.0288696, alpha: 1
Epoch [1/2] - sample 301/1000: loss 0.17157, alpha: 1
Epoch [1/2] - sample 311/1000: loss 0.196899, alpha: 1
Epoch [1/2] - sample 321/1000: loss 0.0112, alpha: 1
Epoch [1/2] - sample 331/1000: loss 0.0223694, alpha: 1
Epoch [1/2] - sample 341/1000: loss 0.163147, alpha: 1
Epoch [1/2] - sample 351/1000: loss 0.292755, alpha: 1
Epoch [1/2] - sample 361/1000: loss 0.0786133, alpha: 1
Epoch [1/2] - sample 371/1000: loss 0.0858459, alpha: 1
Epoch [1/2] - sample 381/1000: loss 0.133209, alpha: 1
Epoch [1/2] - sample 391/1000: loss 0.632751, alpha: 1
Epoch [1/2] - sample 401/1000: loss 0.250061, alpha: 1
Epoch [1/2] - sample 411/1000: loss 0.167023, alpha: 1
Epoch [1/2] - sample 421/1000: loss 0.394287, alpha: 1
Epoch [1/2] - sample 431/1000: loss 0.156006, alpha: 1
Epoch [1/2] - sample 441/1000: loss 0.0598755, alpha: 1
Epoch [1/2] - sample 451/1000: loss 0.0535889, alpha: 1
Epoch [1/2] - sample 461/1000: loss 0.028656, alpha: 1
Epoch [1/2] - sample 471/1000: loss 0.0435791, alpha: 1
Epoch [1/2] - sample 481/1000: loss 0.0141296, alpha: 1
Epoch [1/2] - sample 491/1000: loss 0.0913696, alpha: 1
Epoch [1/2] - sample 501/1000: loss 0.068573, alpha: 1
Epoch [1/2] - sample 511/1000: loss 0.158112, alpha: 1
Epoch [1/2] - sample 521/1000: loss 0.00363159, alpha: 1
Epoch [1/2] - sample 531/1000: loss 0.0857849, alpha: 1
Epoch [1/2] - sample 541/1000: loss 0.428406, alpha: 1
Epoch [1/2] - sample 551/1000: loss 0.38858, alpha: 1
Epoch [1/2] - sample 561/1000: loss 0.420715, alpha: 1
Epoch [1/2] - sample 571/1000: loss 0.0562744, alpha: 1
Epoch [1/2] - sample 581/1000: loss 0.0865784, alpha: 1
Epoch [1/2] - sample 591/1000: loss 0.00808716, alpha: 1
Epoch [1/2] - sample 601/1000: loss 0.039093, alpha: 1
Epoch [1/2] - sample 611/1000: loss 0.265869, alpha: 1
Epoch [1/2] - sample 621/1000: loss 0.0244446, alpha: 1
Epoch [1/2] - sample 631/1000: loss 0.00994873, alpha: 1
Epoch [1/2] - sample 641/1000: loss 0.00427246, alpha: 1
Epoch [1/2] - sample 651/1000: loss 0.275635, alpha: 1
Epoch [1/2] - sample 661/1000: loss 0.0356445, alpha: 1
Epoch [1/2] - sample 671/1000: loss 0.0499878, alpha: 1
Epoch [1/2] - sample 681/1000: loss 0.0666809, alpha: 1
Epoch [1/2] - sample 691/1000: loss 0.00524902, alpha: 1
Epoch [1/2] - sample 701/1000: loss 0.169067, alpha: 1
Epoch [1/2] - sample 711/1000: loss 0.0648499, alpha: 1
Epoch [1/2] - sample 721/1000: loss 0.057312, alpha: 1
Epoch [1/2] - sample 731/1000: loss 0.0431213, alpha: 1
Epoch [1/2] - sample 741/1000: loss 0.119263, alpha: 1
Epoch [1/2] - sample 751/1000: loss 0.075531, alpha: 1
Epoch [1/2] - sample 761/1000: loss 0.0906372, alpha: 1
Epoch [1/2] - sample 771/1000: loss 0.000762939, alpha: 1
Epoch [1/2] - sample 781/1000: loss 0.037384, alpha: 1
Epoch [1/2] - sample 791/1000: loss 0.0726929, alpha: 1
Epoch [1/2] - sample 801/1000: loss 0.15744, alpha: 1
Epoch [1/2] - sample 811/1000: loss 0.0482178, alpha: 1
Epoch [1/2] - sample 821/1000: loss 0.0919189, alpha: 1
Epoch [1/2] - sample 831/1000: loss 0.334381, alpha: 1
Epoch [1/2] - sample 841/1000: loss 0.0322266, alpha: 1
Epoch [1/2] - sample 851/1000: loss 0.0406494, alpha: 1
Epoch [1/2] - sample 861/1000: loss 0.0963135, alpha: 1
Epoch [1/2] - sample 871/1000: loss 0.0389404, alpha: 1
Epoch [1/2] - sample 881/1000: loss 0.317932, alpha: 1
Epoch [1/2] - sample 891/1000: loss 0.00744629, alpha: 1
Epoch [1/2] - sample 901/1000: loss 0.00137329, alpha: 1
Epoch [1/2] - sample 911/1000: loss 0.00323486, alpha: 1
Epoch [1/2] - sample 921/1000: loss 0.00201416, alpha: 1
Epoch [1/2] - sample 931/1000: loss 0.125793, alpha: 1
Epoch [1/2] - sample 941/1000: loss 0.0516663, alpha: 1
Epoch [1/2] - sample 951/1000: loss 0.00866699, alpha: 1
Epoch [1/2] - sample 961/1000: loss 0.137695, alpha: 1
Epoch [1/2] - sample 971/1000: loss 0.0923462, alpha: 1
Epoch [1/2] - sample 981/1000: loss 0.00445557, alpha: 1
Epoch [1/2] - sample 991/1000: loss 0.0764771, alpha: 1
Trainable epoch 0 average loss 0.159785
Epoch [2/2] - sample 1/1000: loss 0.0507507, alpha: 1
Epoch [2/2] - sample 11/1000: loss 0.0384827, alpha: 1
Epoch [2/2] - sample 21/1000: loss 0.017395, alpha: 1
Epoch [2/2] - sample 31/1000: loss 0.296661, alpha: 1
Epoch [2/2] - sample 41/1000: loss 0.0810852, alpha: 1
Epoch [2/2] - sample 51/1000: loss 0.0340881, alpha: 1
Epoch [2/2] - sample 61/1000: loss 0.0010376, alpha: 1
Epoch [2/2] - sample 71/1000: loss 0.00415039, alpha: 1
Epoch [2/2] - sample 81/1000: loss 0.0113525, alpha: 1
Epoch [2/2] - sample 91/1000: loss 0.224304, alpha: 1
Epoch [2/2] - sample 101/1000: loss 0.0822449, alpha: 1
Epoch [2/2] - sample 111/1000: loss 0.00335693, alpha: 1
Epoch [2/2] - sample 121/1000: loss 0.0198975, alpha: 1
Epoch [2/2] - sample 131/1000: loss 0.0123901, alpha: 1
Epoch [2/2] - sample 141/1000: loss 0.0396729, alpha: 1
Epoch [2/2] - sample 151/1000: loss 0.00231934, alpha: 1
Epoch [2/2] - sample 161/1000: loss 0.0291748, alpha: 1
Epoch [2/2] - sample 171/1000: loss 0.0108337, alpha: 1
Epoch [2/2] - sample 181/1000: loss 0.128204, alpha: 1
Epoch [2/2] - sample 191/1000: loss 0.000396729, alpha: 1
Epoch [2/2] - sample 201/1000: loss 0.0369873, alpha: 1
Epoch [2/2] - sample 211/1000: loss 0.00842285, alpha: 1
Epoch [2/2] - sample 221/1000: loss 0.0057373, alpha: 1
Epoch [2/2] - sample 231/1000: loss 0.098877, alpha: 1
Epoch [2/2] - sample 241/1000: loss 0.0116272, alpha: 1
Epoch [2/2] - sample 251/1000: loss 0.00201416, alpha: 1
Epoch [2/2] - sample 261/1000: loss 0.0057373, alpha: 1
Epoch [2/2] - sample 271/1000: loss 0.00552368, alpha: 1
Epoch [2/2] - sample 281/1000: loss 0.0797119, alpha: 1
Epoch [2/2] - sample 291/1000: loss 0.000427246, alpha: 1
Epoch [2/2] - sample 301/1000: loss 0.0134888, alpha: 1
Epoch [2/2] - sample 311/1000: loss 0.0134583, alpha: 1
Epoch [2/2] - sample 321/1000: loss 0.0125732, alpha: 1
Epoch [2/2] - sample 331/1000: loss 0.038208, alpha: 1
Epoch [2/2] - sample 341/1000: loss 0.0543823, alpha: 1
Epoch [2/2] - sample 351/1000: loss 0.042572, alpha: 1
Epoch [2/2] - sample 361/1000: loss 0.0100098, alpha: 1
Epoch [2/2] - sample 371/1000: loss 0.00466919, alpha: 1
Epoch [2/2] - sample 381/1000: loss 0.0263062, alpha: 1
Epoch [2/2] - sample 391/1000: loss 0.0310669, alpha: 1
Epoch [2/2] - sample 401/1000: loss 0.094696, alpha: 1
Epoch [2/2] - sample 411/1000: loss 0.00860596, alpha: 1
Epoch [2/2] - sample 421/1000: loss 0.033844, alpha: 1
Epoch [2/2] - sample 431/1000: loss 0.00531006, alpha: 1
Epoch [2/2] - sample 441/1000: loss 0.000518799, alpha: 1
Epoch [2/2] - sample 451/1000: loss 0.034668, alpha: 1
Epoch [2/2] - sample 461/1000: loss 0.00396729, alpha: 1
Epoch [2/2] - sample 471/1000: loss 0.00714111, alpha: 1
Epoch [2/2] - sample 481/1000: loss 0.0177002, alpha: 1
Epoch [2/2] - sample 491/1000: loss 0.0230103, alpha: 1
Epoch [2/2] - sample 501/1000: loss 0.0213318, alpha: 1
Epoch [2/2] - sample 511/1000: loss 0.000335693, alpha: 1
Epoch [2/2] - sample 521/1000: loss 0.0181274, alpha: 1
Epoch [2/2] - sample 531/1000: loss 0.0167236, alpha: 1
Epoch [2/2] - sample 541/1000: loss 0.00210571, alpha: 1
Epoch [2/2] - sample 551/1000: loss 0.0305176, alpha: 1
Epoch [2/2] - sample 561/1000: loss 0.00604248, alpha: 1
Epoch [2/2] - sample 571/1000: loss 0.0163574, alpha: 1
Epoch [2/2] - sample 581/1000: loss 0.00540161, alpha: 1
Epoch [2/2] - sample 591/1000: loss 0.00338745, alpha: 1
Epoch [2/2] - sample 601/1000: loss 0.00128174, alpha: 1
Epoch [2/2] - sample 611/1000: loss 0.00189209, alpha: 1
Epoch [2/2] - sample 621/1000: loss 0.000671387, alpha: 1
Epoch [2/2] - sample 631/1000: loss 0.00332642, alpha: 1
Epoch [2/2] - sample 641/1000: loss 0.00576782, alpha: 1
Epoch [2/2] - sample 651/1000: loss 0.00674438, alpha: 1
Epoch [2/2] - sample 661/1000: loss 0.00958252, alpha: 1
Epoch [2/2] - sample 671/1000: loss 0.00531006, alpha: 1
Epoch [2/2] - sample 681/1000: loss 0.0090332, alpha: 1
Epoch [2/2] - sample 691/1000: loss 0.0065918, alpha: 1
Epoch [2/2] - sample 701/1000: loss 0.015564, alpha: 1
Epoch [2/2] - sample 711/1000: loss 0.0227661, alpha: 1
Epoch [2/2] - sample 721/1000: loss 0.0402832, alpha: 1
Epoch [2/2] - sample 731/1000: loss 0.00396729, alpha: 1
Epoch [2/2] - sample 741/1000: loss 0.012085, alpha: 1
Epoch [2/2] - sample 751/1000: loss 0.0098877, alpha: 1
Epoch [2/2] - sample 761/1000: loss 0.00549316, alpha: 1
Epoch [2/2] - sample 771/1000: loss 0.0580139, alpha: 1
Epoch [2/2] - sample 781/1000: loss 0.00302124, alpha: 1
Epoch [2/2] - sample 791/1000: loss 0.00177002, alpha: 1
Epoch [2/2] - sample 801/1000: loss 0.0316162, alpha: 1
Epoch [2/2] - sample 811/1000: loss 0.00708008, alpha: 1
Epoch [2/2] - sample 821/1000: loss 0.0131226, alpha: 1
Epoch [2/2] - sample 831/1000: loss 0.011261, alpha: 1
Epoch [2/2] - sample 841/1000: loss 0.0015564, alpha: 1
Epoch [2/2] - sample 851/1000: loss 0.00891113, alpha: 1
Epoch [2/2] - sample 861/1000: loss 0.00302124, alpha: 1
Epoch [2/2] - sample 871/1000: loss 0.0289612, alpha: 1
Epoch [2/2] - sample 881/1000: loss 0.00152588, alpha: 1
Epoch [2/2] - sample 891/1000: loss 0.00701904, alpha: 1
Epoch [2/2] - sample 901/1000: loss 0.000976562, alpha: 1
Epoch [2/2] - sample 911/1000: loss 0.0169983, alpha: 1
Epoch [2/2] - sample 921/1000: loss 0.0230713, alpha: 1
Epoch [2/2] - sample 931/1000: loss 0.00857544, alpha: 1
Epoch [2/2] - sample 941/1000: loss 0.00442505, alpha: 1
Epoch [2/2] - sample 951/1000: loss 0.0359192, alpha: 1
Epoch [2/2] - sample 961/1000: loss 0.000488281, alpha: 1
Epoch [2/2] - sample 971/1000: loss 0.00256348, alpha: 1
Epoch [2/2] - sample 981/1000: loss 0.00280762, alpha: 1
Epoch [2/2] - sample 991/1000: loss 0.0174866, alpha: 1
Trainable epoch 1 average loss 0.027884
INFO: Saved trainable inference results to file: tb_data/csim_results.log
INFO: Saved trainable loss trace to file: tb_data/training/loss.dat
INFO: Saved trainable alpha trace to file: tb_data/training/alpha.dat
INFO: Saved trainable dense0 weight trace to file: tb_data/training/dense0/weights.dat
INFO: Saved trainable dense0 bias trace to file: tb_data/training/dense0/biases.dat
INFO: [SIM 211-1] CSim done with 0 errors.
INFO: [SIM 211-3] *************** CSIM finish ***************
INFO: [HLS 200-2161] Finished Command csim_design Elapsed time: 00:00:09; Allocated memory: 0.000 MB.
***** C SIMULATION COMPLETED IN 0h0m11s *****
INFO: [HLS 200-112] Total CPU user time: 11.85 seconds. Total CPU system time: 1.27 seconds. Total elapsed time: 17.42 seconds; peak allocated memory: 336.258 MB.
INFO: [vitis-run 60-791] Total elapsed time: 0h 0m 19s
INFO: [vitis-run 60-1662] Stopping dispatch session having empty uuid.
CSynthesis report not found.
Vivado synthesis report not found.
Cosim report not found.
Timing report not found.
Loading results from tb_data and plotting
First, we load the results from the tb_data directory, which is where ENABOL saves all the traces and stats during the training run. We can load the data using the TestbenchData class, which provides a convenient interface to access all the traces and stats.
from enabol import TestbenchData

tb = TestbenchData.from_dir(
    hls_model.config.get_output_dir(),
    load_weights=True,   # True, False, or ["dense0", "dense1"]
)

tb.frame                    # top-level traces only: loss, alpha, etc.
tb.layers["dense0"].weights # raw weight evolution dataframe
tb.layers["dense0"].biases  # raw bias evolution dataframe
tb.layers["dense0"].stats   # per-layer scalar stats
tb.stats_frame              # all layer stats, namespaced
tb.scalar_frame             # tb.frame + tb.stats_frame
And finally we can plot them:
tb.plot_training(
    metrics=["loss", "alpha", "dense0.weights.mean", "dense0.weights.norm_l2"],
    window_size=30,
)
Results: No controller
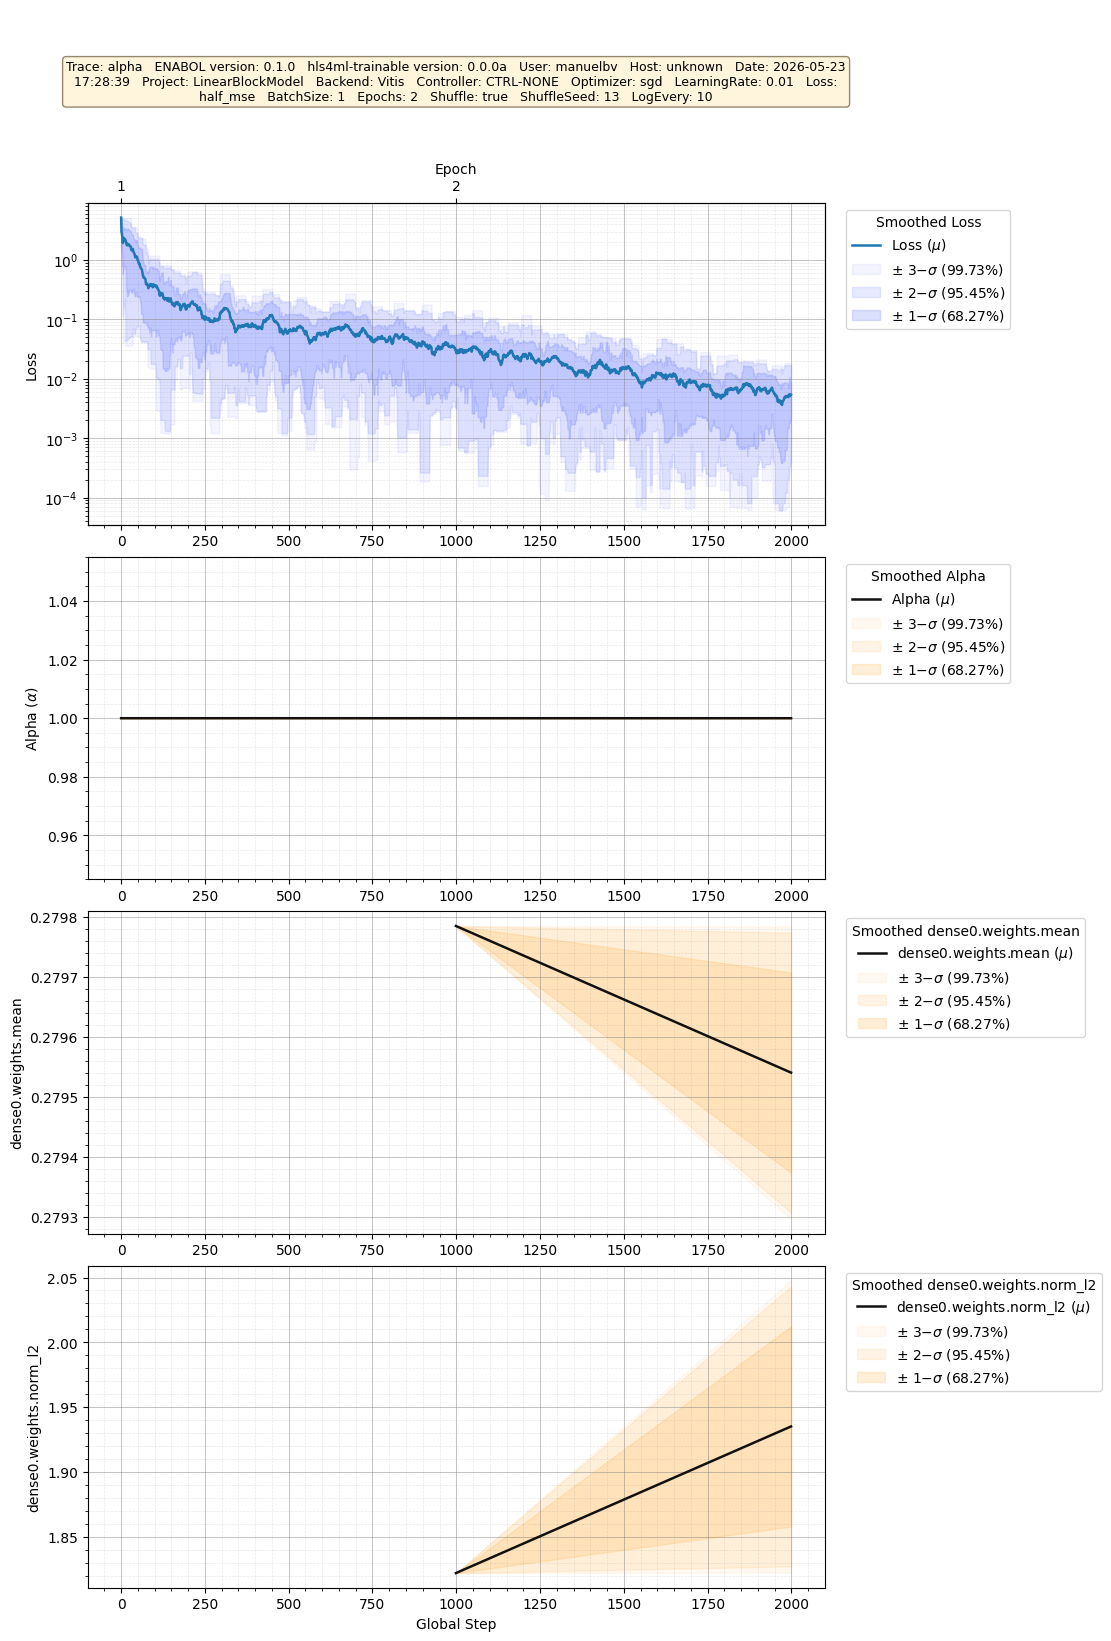
In this case no controller was used, but the learning rate is not too high, and we are not running for many epochs, so we expect the system to be stable and to converge to a low loss. The results are shown in the plot below, where we can see that the loss is indeed decreasing and converging to a low value.
Results: CTRL-GT-0
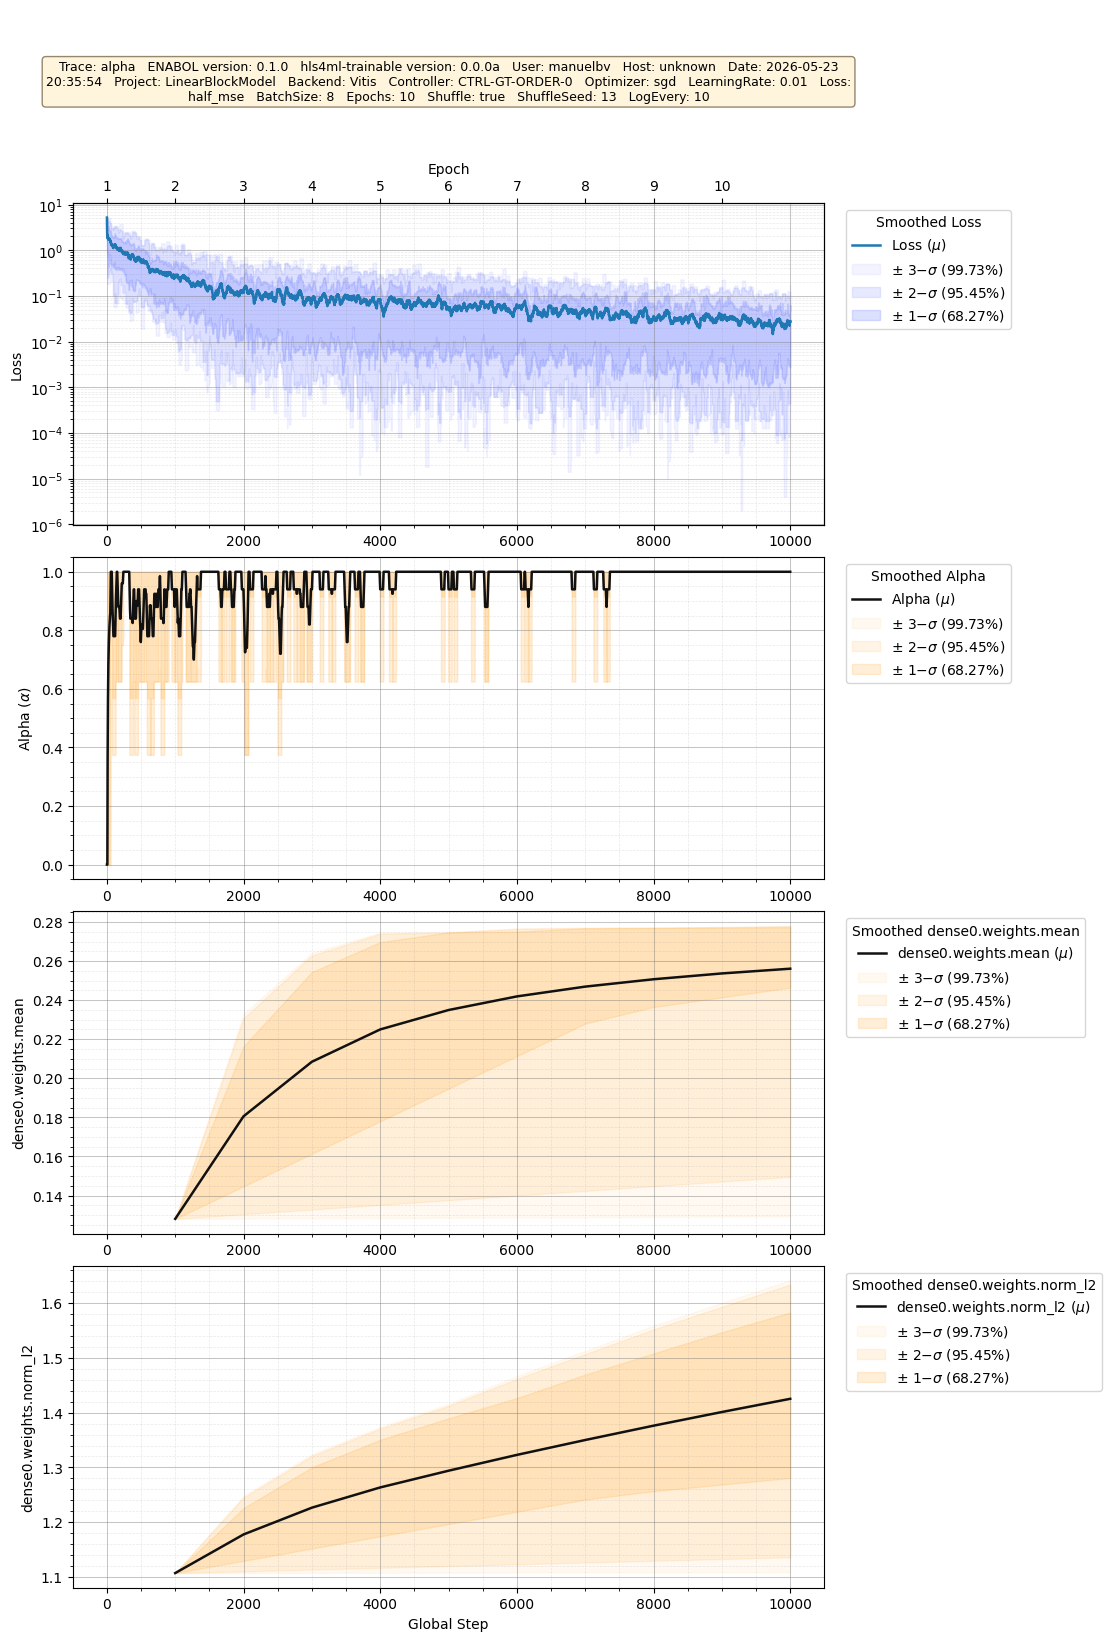
The results for using the fast controller CTRL-GT-0 are shown in the plot below. We can see that the loss is decreasing and converging to a low value, which confirms that our simulation is working and that our compilation for this case is also okay. Also, note how the value starts at (as expected), but then jumps quickly to and stays there.
Conclusions
In this tutorial we have shown how to use ENABOL to run a trainable HLS simulation using the Vitis backend. We have also shown how to load the results from the testbench data and plot them. Finally, we have shown the results for the case where no controller is used, which confirms that our simulation is working and that our compilation for this simple case is okay. In the next sections we will show the results for different controllers and compare them with the theoretical predictions.